On this page
From incomplete observations to informed action
AI systems encounter a world they can only partially observe. Our research asks how they can build useful representations, anticipate change, and choose actions as new evidence arrives.
We connect multimodal understanding, 3D geometry, memory, and generative modeling across four research directions. Robotics, transportation systems, and public safety provide settings where the quality of a prediction matters for real decisions.
Multimodal understanding
How can AI explain events when the evidence is incomplete or conflicting?
The same event can look different across cameras, languages, and contexts. We study representations that connect entities, actions, and their relationships across video, speech, text, and structured knowledge. Our goal is reasoning that explains its evidence and revises its conclusions as new observations arrive.
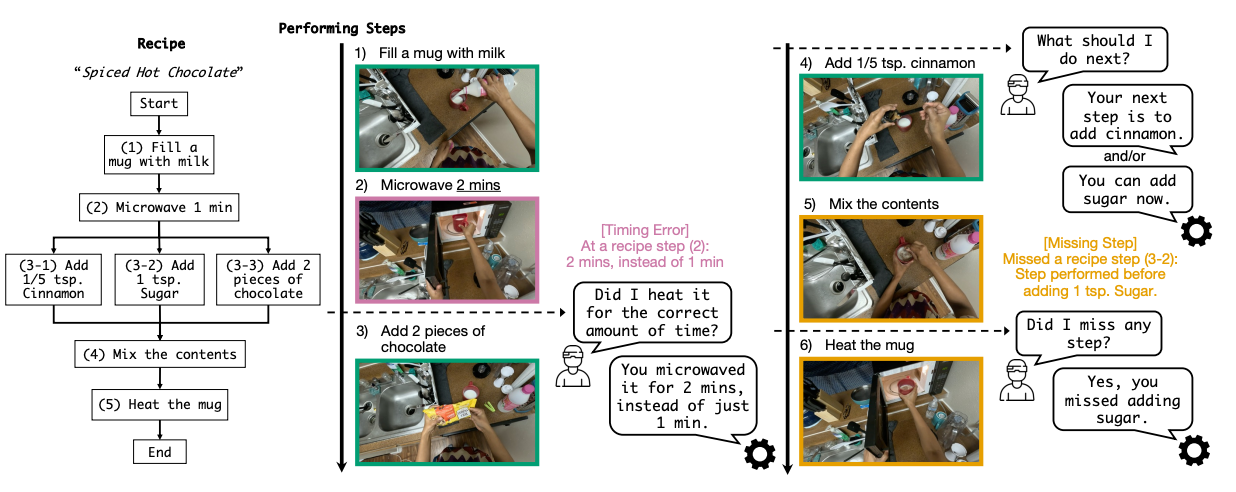
Directions to explore: temporal and event reasoning, multimodal memory, and learning from conflicting evidence. Applications include interactive assistance, video analysis, and human–AI collaboration.
World models
How can world models predict change and guide decisions?
We develop world models that connect spatial structure, memory, and dynamics with the consequences of actions. By learning from multimodal experience, these models can provide a basis for simulation and planning beyond current observations. We study which predictions help decisions, how uncertainty should be represented, and how new evidence should update a model.
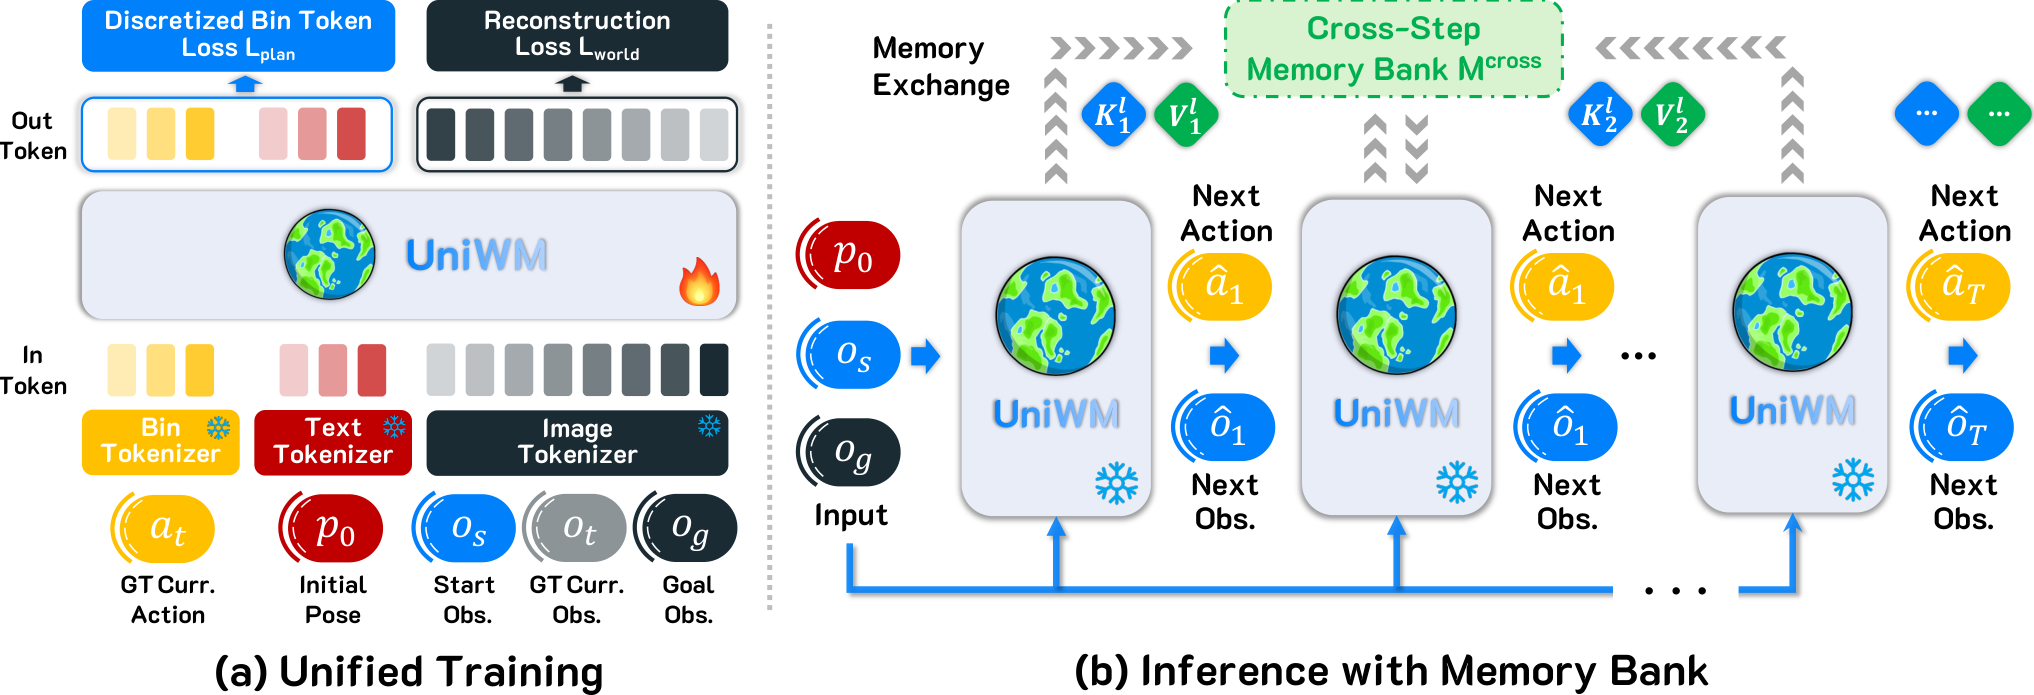
Directions to explore: persistent 3D representations, long-horizon memory, action-conditioned prediction, and learning from prediction errors. These questions connect to robot planning, digital twins, and decision support.
Embodied intelligence
How can agents adapt as people, tasks, and environments change?
Instructions rarely specify every step, and actions change what an agent can observe. We study how perception, language, and spatial reasoning guide navigation and physical interaction. Human-aware benchmarks let us examine success alongside collisions, social context, and adaptation to unfamiliar situations.
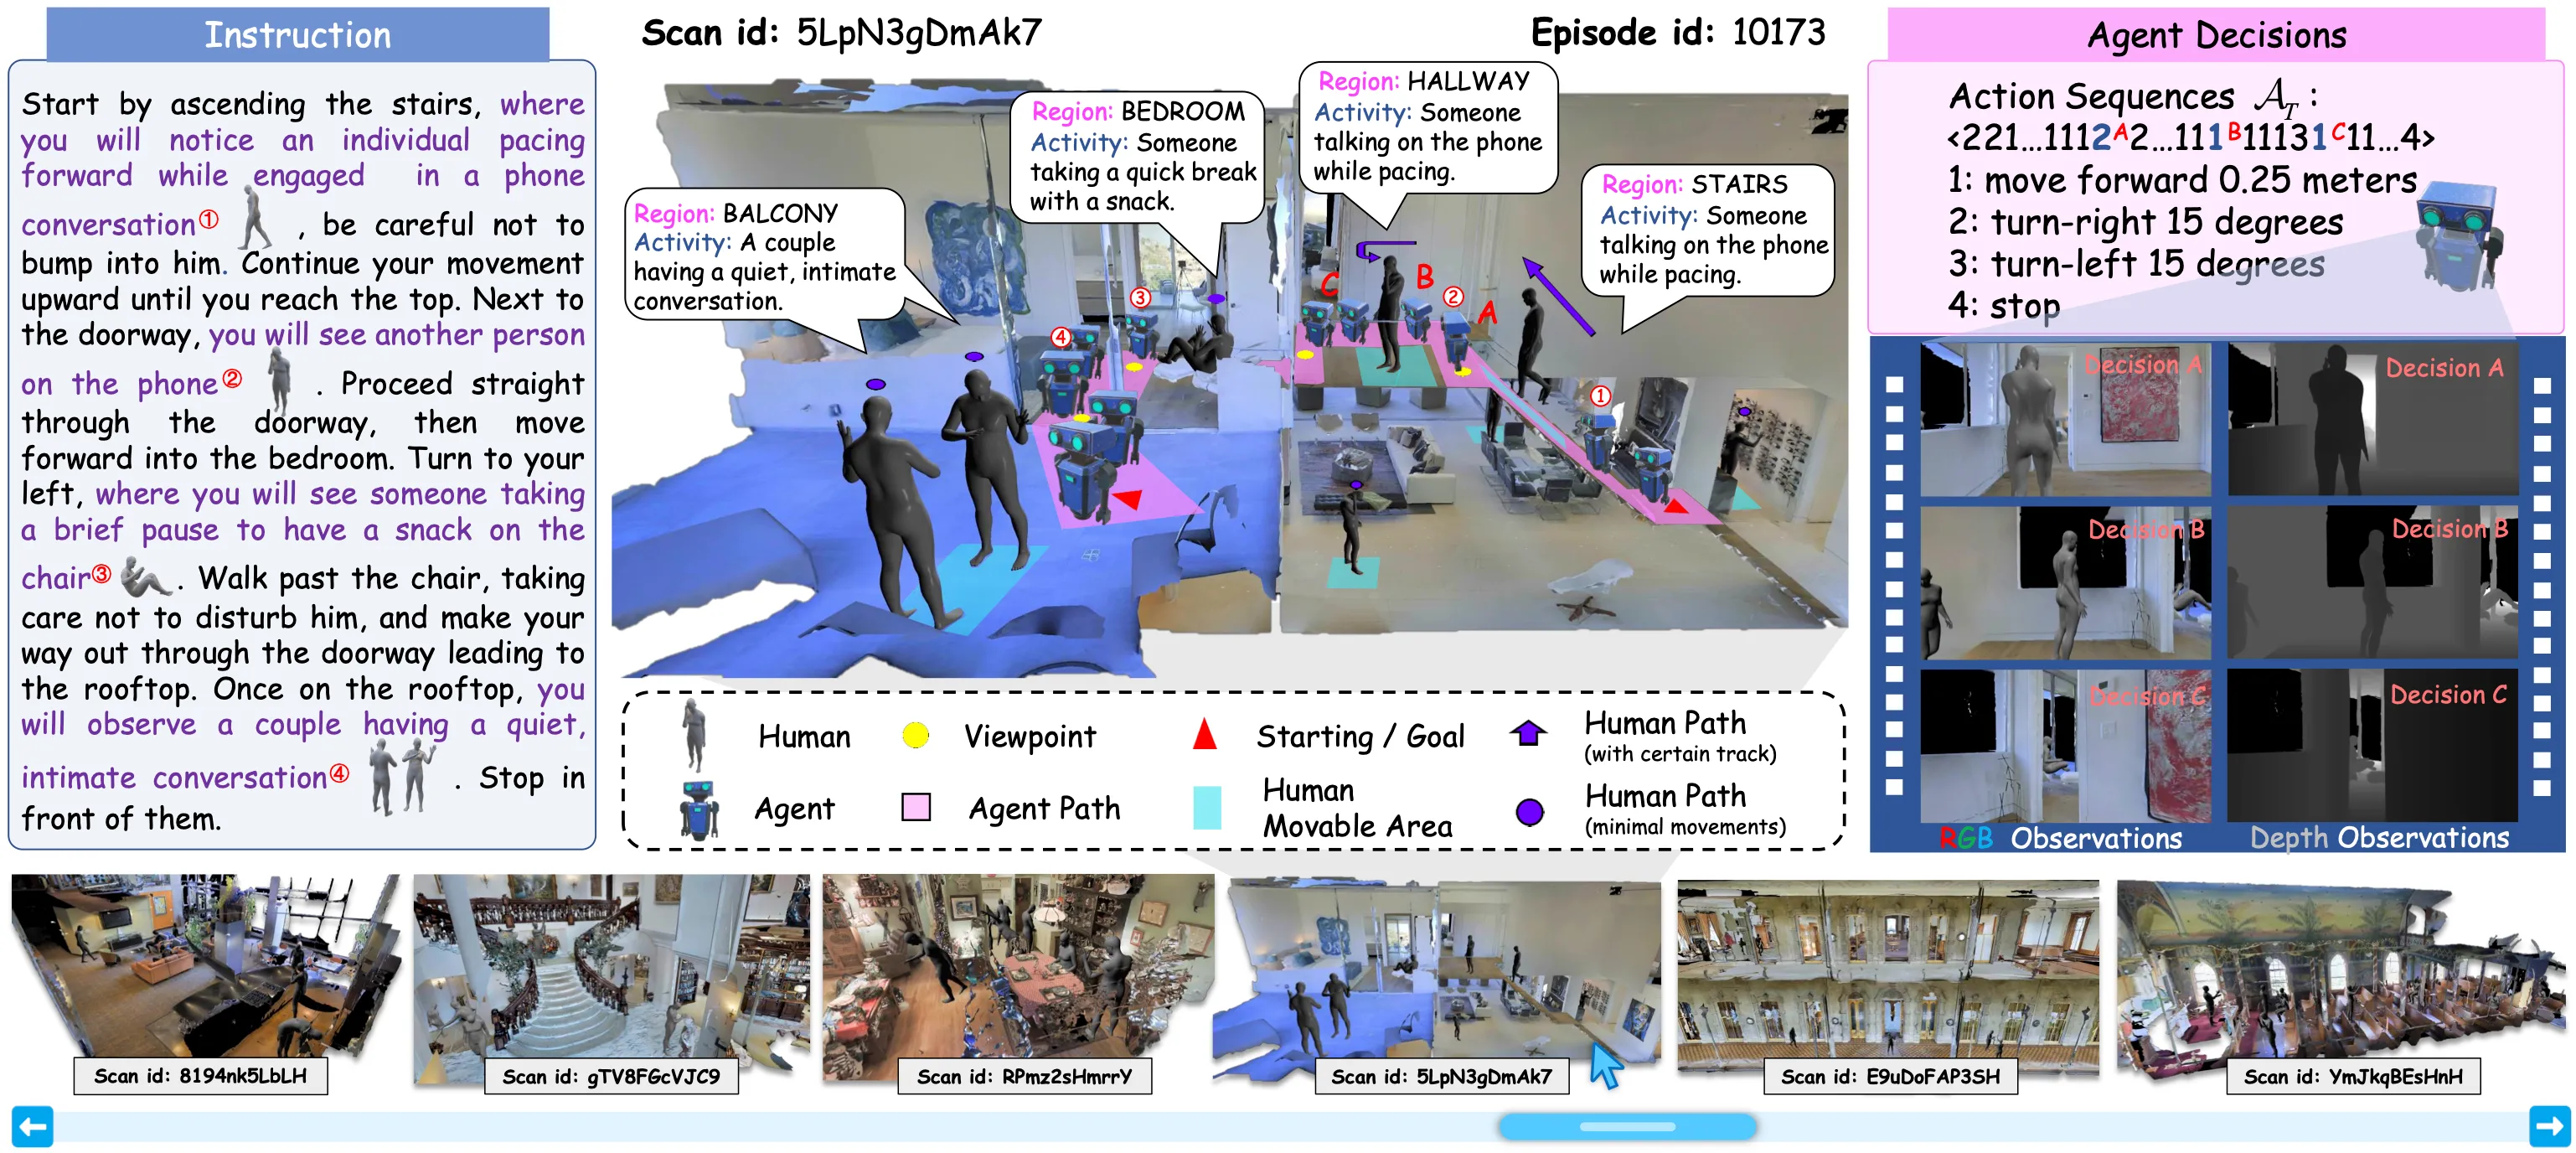
Directions to explore: instruction-following, navigation around people, and perception for manipulation. We aim to support assistive robots, logistics and manufacturing, infrastructure inspection, and emergency response.
Transportation & Public Safety
What has changed, where might risks emerge, and what needs attention?
We connect 3D geometry, semantic understanding, and video analysis to study infrastructure and human activity. A central challenge is distinguishing meaningful changes from viewpoint, lighting, and occlusion effects. Our research combines information across views and time to support maps that can be updated and events that can be understood in context.
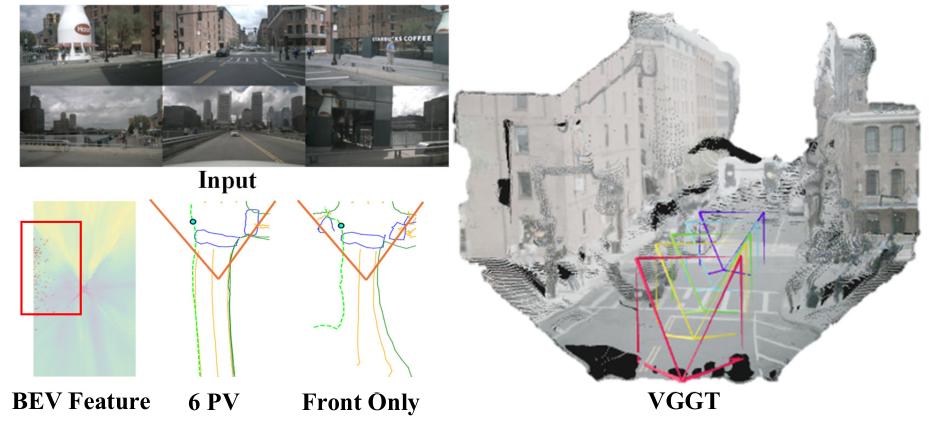
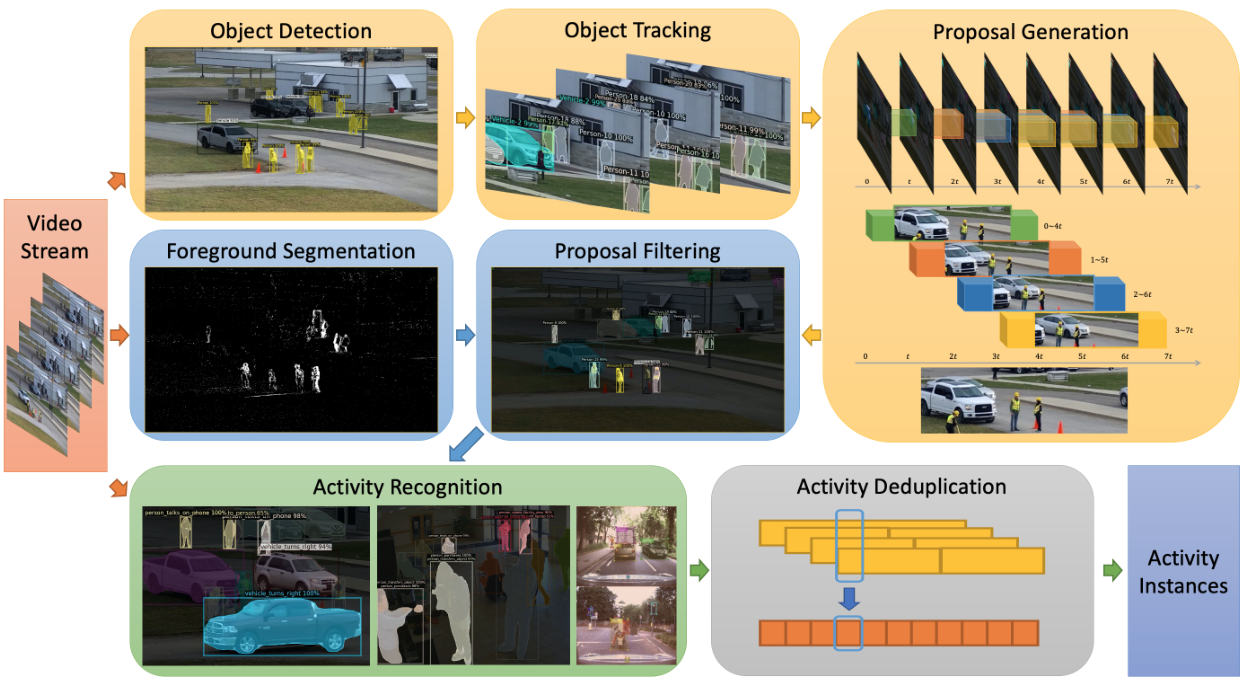
Directions to explore: infrastructure monitoring, traffic and crowd analysis, uncertainty-aware mapping, and targeted data collection. Our goal is to inform inspection, asset management, hazard assessment, and emergency response.
Reliable & efficient AI
Across these directions, we study how models can remain useful when data, environments, and computing resources change.
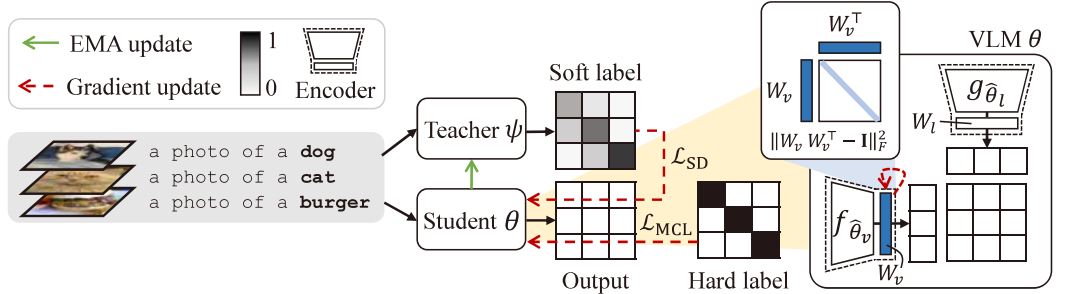
Reliability under change
Robust adaptation, calibrated confidence, and evaluation that exposes failure cases.
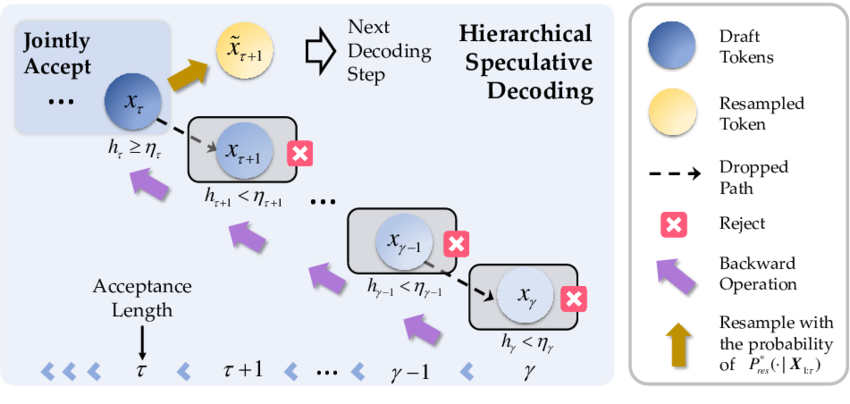
Efficient inference
Faster reasoning and generation while preserving the behavior that downstream tasks depend on.
We evaluate accuracy alongside decision quality, robustness, and computational cost, using controlled comparisons and realistic changes in observations.
Research foundations
Transportation research at UW
Two projects funded by the U.S. Department of Transportation through PacTrans support our research in 3D urban scene reconstruction and transportation asset mapping.
Systems and public impact
Professor Cheng’s earlier work at Carnegie Mellon University includes core technical leadership in DARPA KAIROS and KAIROS Plus, alongside research in video activity analysis, transportation, and manufacturing digital twins.
His technical contributions to visual journalism include work for The Washington Post and The New York Times, including The Post’s reporting recognized with the 2022 Pulitzer Prize for Public Service.
Research opportunities
Students can contribute through model development, datasets and benchmarks, simulation, or systems research. We welcome interests spanning computer vision, machine learning, robotics, and transportation.
Tell us which research question interests you, what you have worked on, and what you would like to learn. Prospective students, current UW students, and research collaborators can find the appropriate contact and advising routes below.